A patient-data transmission is held for review.
A four-model consensus roster deliberates before anything moves.
- Proposed action
- Transmit a patient’s diagnosis and record number to an out-of-network endpoint.
- Configured authority
- “In-network patient record lookup only.”
- Routing basis
- The action stays inside the agent’s patient-record domain, so the deterministic scope check does not classify it as a categorical no-authority violation; the regulated-health-data policy class then fires on the diagnosis and record-number fields and the gate escalates it to a human.
Mechanism and limits
A care-coordination agent whose configured authority reads “in-network patient record lookup only” tries to transmit a patient’s diagnosis and record number to an out-of-network endpoint. Why this escalates rather than blocks: the gate blocks only categorical no-authority actions — a read-only agent mutating, an explicitly denied verb, an action outside a closed allow-list. This one stays inside the agent’s patient-record domain, so the deterministic scope check does not classify it as a categorical no-authority violation; the regulated-health-data policy class then fires on the diagnosis and record-number fields and the gate escalates it to a human — the semantics an independent red-team validated. Stations 01–04 inspect or derive evidence from this one decision; later stations run further actions or read recorded history back.
The record doesn’t ask to be believed. It’s signed.
This station reads the signature off the decision you just ran, fetches Veridect’s published public key live, and pins the key in the record against the published one — the same check a real auditor performs against the published key.
Mechanism and limits
An audit log you have to take on faith isn’t evidence. Every governed decision here is sealed twice: a SHA-256 hash proves nothing in the record changed, and an Ed25519 signature over that hash proves who sealed it.
Verify the decision. Then tamper with it — and watch the math catch you.
First this station verifies the genuine record: hash, signature, and an independent re-derivation of the verdict.
Mechanism and limits
The governance verdict lives in deterministic code, so it can be re-derived exactly from the inputs sealed in the bundle — no need to re-run the models (the consensus summary is attested, not reproduced). Then it does what a vendor video never dares: it edits one field of the record — rewriting the verdict the way a bad actor would — and submits the forgery.
Turn the decision into evidence an underwriter can act on.
This station converts the governed decision into an underwriting-grade evidence record: five neutral evidence categories, structural identifiers only — no free text, no personal data (the payload hash attests the full action without exposing it) — safe to hand to a third party.
Mechanism and limits
AI actions are becoming insurable events — and insurers need evidence, not assurances. Veridect is not an insurer; this record is not actuarial pricing, a certification, or coverage.
No single agent breaks the rules. The workflow does.
Three agents share one task: an intake agent reads a customer’s SSN and bank account, an enrichment agent reads a patient diagnosis, then a reporting agent — which touched none of that data itself — tries to send an outbound summary. This station runs all three gate calls live, sharing one workflow ID.
Mechanism and limits
Each agent stays inside its own scope. Constellation watches the workflow as a whole, attributes each agent’s part, and escalates the final egress to a human. It is escalate-only: it adds a human check, never blocks on its own, never auto-approves.
The theft that never looks like a theft.
One agent, one session, four ordinary steps: it reads a customer contact detail, then an account number, then an employment attribute — each read squarely inside the scope it was granted — and then sends a routine summary out. This station runs all four gate calls live on a session ID created for this run alone.
Mechanism and limits
No single call breaks a rule, so nothing in a per-action gate’s rulebook stops any of them — watch each step get judged on its own. The engine keeps a running count of what this session has already seen — field names only, never the values — and escalates the outbound step to a human once the accumulation crosses the line. Escalate-only, like every policy class: it adds a person, it never blocks on its own.
An escalation only counts if the human actually looked.
Routing risky actions to a human is the easy half. The hard half is proving the human didn’t wave them through in three seconds.
Mechanism and limits
Each review is appended once to the same tamper-evident chain as the verdict — opaque codes only, no emails, no free text — and across a tenant’s reviews the layer reads a rubber-stamp risk band: weighted 65% toward approvals that ignored live model dissent, 25% toward approvals with nothing changed, 10% toward unusually fast reviews. It reads the pattern across a team — never a score on an individual — and below five reviews it refuses to read a pattern at all.
Who, cryptographically, is asking? Two impostors — then the real thing.
This station fires two impostor calls at a tenant that requires identity — one with no envelope at all, one with a forged signature — and both are refused before a single model is consulted, at zero inference cost.
Mechanism and limits
In an agent fleet, a name in a request is not an identity. Here every agent carries its own Ed25519 keypair, every request arrives with a signed identity envelope, and delegated authority travels as a signed chain that can only narrow, never grow. Then it reads back a genuine chain-verified decision from the ledger, hop by hop.
Evidence in the regulator’s language — assembled from the live ledger.
The engine maps its own sealed records onto the EU AI Act article by article — risk management, record-keeping, transparency, human oversight, accuracy & robustness, deployer obligations, incident reporting — each article backed by the real audit records that support it, with an explicit non-coverage note wherever the layer does not reach.
Mechanism and limits
When the question is “show us how this is governed”, raw logs are not an answer. The mapping is fixed in code; the legal determination stays with your counsel. It also drafts an Article 73 serious-incident skeleton straight from the escalation you watched in station 00. And that package is wired all the way through — demonstrated end-to-end against a live ServiceNow instance, arriving as a standard incident record via the core Table API every instance ships with, no GRC module required.
Facts an underwriter can use. Deliberately not a score.
This station pulls thirty days of live assurance telemetry for this tenant: decision mix by day, deterministic policy-class fire rates, identity enforcement, oversight quality, ledger integrity.
Mechanism and limits
Station 03 turned one decision into evidence — an underwriter prices a book of them. Counts, rates, and time statistics only — no free text, no personal data, and deliberately no composite risk score, because an invented number is exactly what a serious risk partner does not want. Veridect is not an insurer; this is evidence for their judgment, not pricing, certification, or coverage.
A refused call never reaches the tool. Watch the counter not move.
This page hosts a sample tool with its own hit counter. The station reads that counter, fires an unidentified call at the live gateway, and reads it again — the refusal shows up on the tool’s side as silence.
Mechanism and limits
Agents increasingly act through MCP tool servers — so Veridect sits between agent and tool, governing every tools/call in flight: identity checked, gate consulted, verdict written into the JSON-RPC response itself. A refused call is never forwarded at all. The identity-verified call from station 08 is the one that went through: same gateway, greenlit, signed, on the ledger.
Can the system attack its own defenses before an adversary does? Inspect its latest self-test.
A gate you never attack is a gate you are taking on faith. This station reads the latest stored run back, live from the engine.
Mechanism and limits
On demand, the four frontier models each author novel attack scenarios against this tenant’s live policy — scope violations, authority ambiguity, financial-threshold probes, protected-data grabs, stealth requests dressed as routine work — and the same deterministic decision core that guards real traffic judges every one in strict isolation: synthetic consensus, zero writes to the evidence ledger, no session state. Every probe the deterministic layer alone would have greenlit is flagged for human review, and on live traffic four model votes stand in front of that layer.
Can you test a policy change against your own history — before you ship it?
Here the engine replays this tenant’s real recorded decisions under a hypothetical policy — the same pure decision core used live and at proof time, zero model calls, zero writes — and reports exactly which verdicts would flip and which policy field drove each flip.
Mechanism and limits
Every threshold change is a bet, and most teams settle it in production. Records that cannot be honestly re-derived are counted not replayable, never guessed. Then this station asks for something the engine refuses: overriding a session-exposure threshold that is attested at decision time rather than re-derivable — and you watch it decline rather than fake an answer.
When one model saw what three missed — is that on the record?
This engine writes every provider dissent into a permanent ledger — who objected, on which verdict, whether they stood alone — and when a later human review resolves the decision, the outcome is recorded against the dissent: vindicated, partially vindicated, or overruled.
Mechanism and limits
Consensus systems have a quiet failure mode: the dissenting vote that was right gets averaged away and forgotten. Counts and rates only, deliberately never a provider ranking — a dissent is evidence of independent disagreement, not a scored error. Free-text dissent reasoning stays sealed inside the tenant’s audit bundles.
Seven hundred innocent agents is the problem. Three identities converging live is the proof.
This station runs the pattern live with three agent identities on a dedicated fleet-enabled tenant: a CRM sync agent, a billing reconciler, and a campaign optimizer each read the same sensitive dimension, squarely authorized — watch the gate clear each one.
Three identities converge here because this tenant’s threshold is three. The same layer has been exercised at ten thousand.
On 10 September 2026, ten thousand distinct agent identities went through the fleet layer on one tenant — one proposed step each, threshold twenty-five: 8,500 confidential reads, 1,000 in-scope sends to an external mailbox, 250 in-scope high-risk transfers, 250 transfers under a read-only grant. The first outbound step held for a person came from identity #30; three had cleared before it, exactly what the threshold specifies. Every one of the 1,496 outbound steps after it was held or blocked. A benign control fleet of ten thousand under the same policy drew zero fleet escalations. A third fleet that sent no identity at all was caught by the tenant-wide counter once pooled reads crossed the line. Then the fast state was wiped — 17,009 keys, verified gone — and the next ordinary outbound step rebuilt the window from the sealed ledger and escalated with all three classes. All 10,000 rulings agreed with an independent re-statement of the policy.
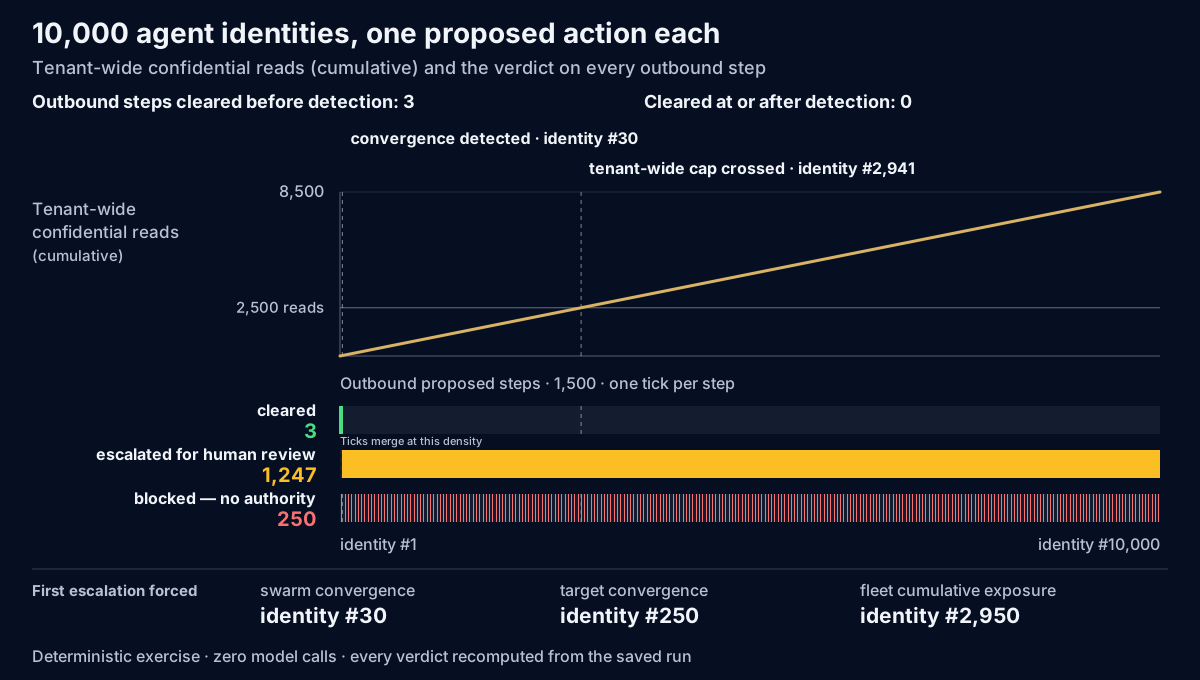
Then the same swarm went through the published system — every ruling real, every record signed.
Between 10 and 11 September 2026 the same swarm — ten thousand identities, the same mix of proposed steps, the same fleet policy — went through the published gate as ordinary API requests on a dedicated tenant, each a real multi-model ruling with three providers responding: 8,487 cleared, 1,263 escalated for human review, 250 blocked. Detection came at identity #30 again; every one of the 1,496 outbound steps after it was held or blocked. A benign control fleet of 300 live rulings drew zero fleet escalations. 10,300 of 10,300 signed records verified offline against the published key; all eleven acceptance checks passed; the run’s tenant keys were revoked at the end.

The fleet-scale exercise is deterministic — the real policy engine and fast-state store, with a unanimous synthetic approve standing in for the model consensus, so every escalation is the fleet layer’s alone. It proves the fleet logic at scale, not the models; the live run is the separate metric — the whole system, models included, on the published deployment — reported beside it and never merged. Disclosed in the record: 120 live rulings, spanning identities #1,298–#1,417, carry an error entry from one provider instead of a stance; the remaining providers cleared the three-provider quorum on every one. Both are our own runs, not an independent red team’s; ten thousand is a count of identities ruled on, not a rate.
Mechanism and limits
Earlier stations watched risk inside one action, one session, or one declared workflow. This is the failure mode beyond all three: many agents that share no workflow, each individually innocent — reads spread across identities so that no per-agent, per-session view ever adds up to anything. Tenant-wide, the engine’s coordination fabric counts distinct identities per dimension — field-name categories and hashed action shapes, never values — and the moment one of those agents turns outbound inside the converged pattern, the send is escalated to a human before it happens. Accumulation is always-on; enforcement is a per-tenant policy knob, set to three here so you can watch it converge in one sitting. Escalate-only, like every policy class — and agent identities are as reported by the integrating platform. The fabric is indifferent to which agent harness each identity runs on: it counts tenant and identity, never framework, so one fleet layer governs many agent harnesses at once, for every action they send through the gate.
One verdict is a decision. The ledger is a governance program.
The Command Center reads the shared tenant’s ledger back live: verdict mix, risk tiers, which policies fired, the agent fleet.
Mechanism and limits
Every governed action this tour ran landed in a tamper-evident ledger — your opening decision, the three-agent workflow and the slow-burn session in this shared sandbox tenant; the identity refusals, the gateway’s refused tool call and the swarm that converged at Station 15 in their own dedicated tenants. Not a dashboard fed by marketing numbers — a view computed from records exactly like the ones you just watched being written.